AI Engineering Skills Roadmap
Summarize with AI:
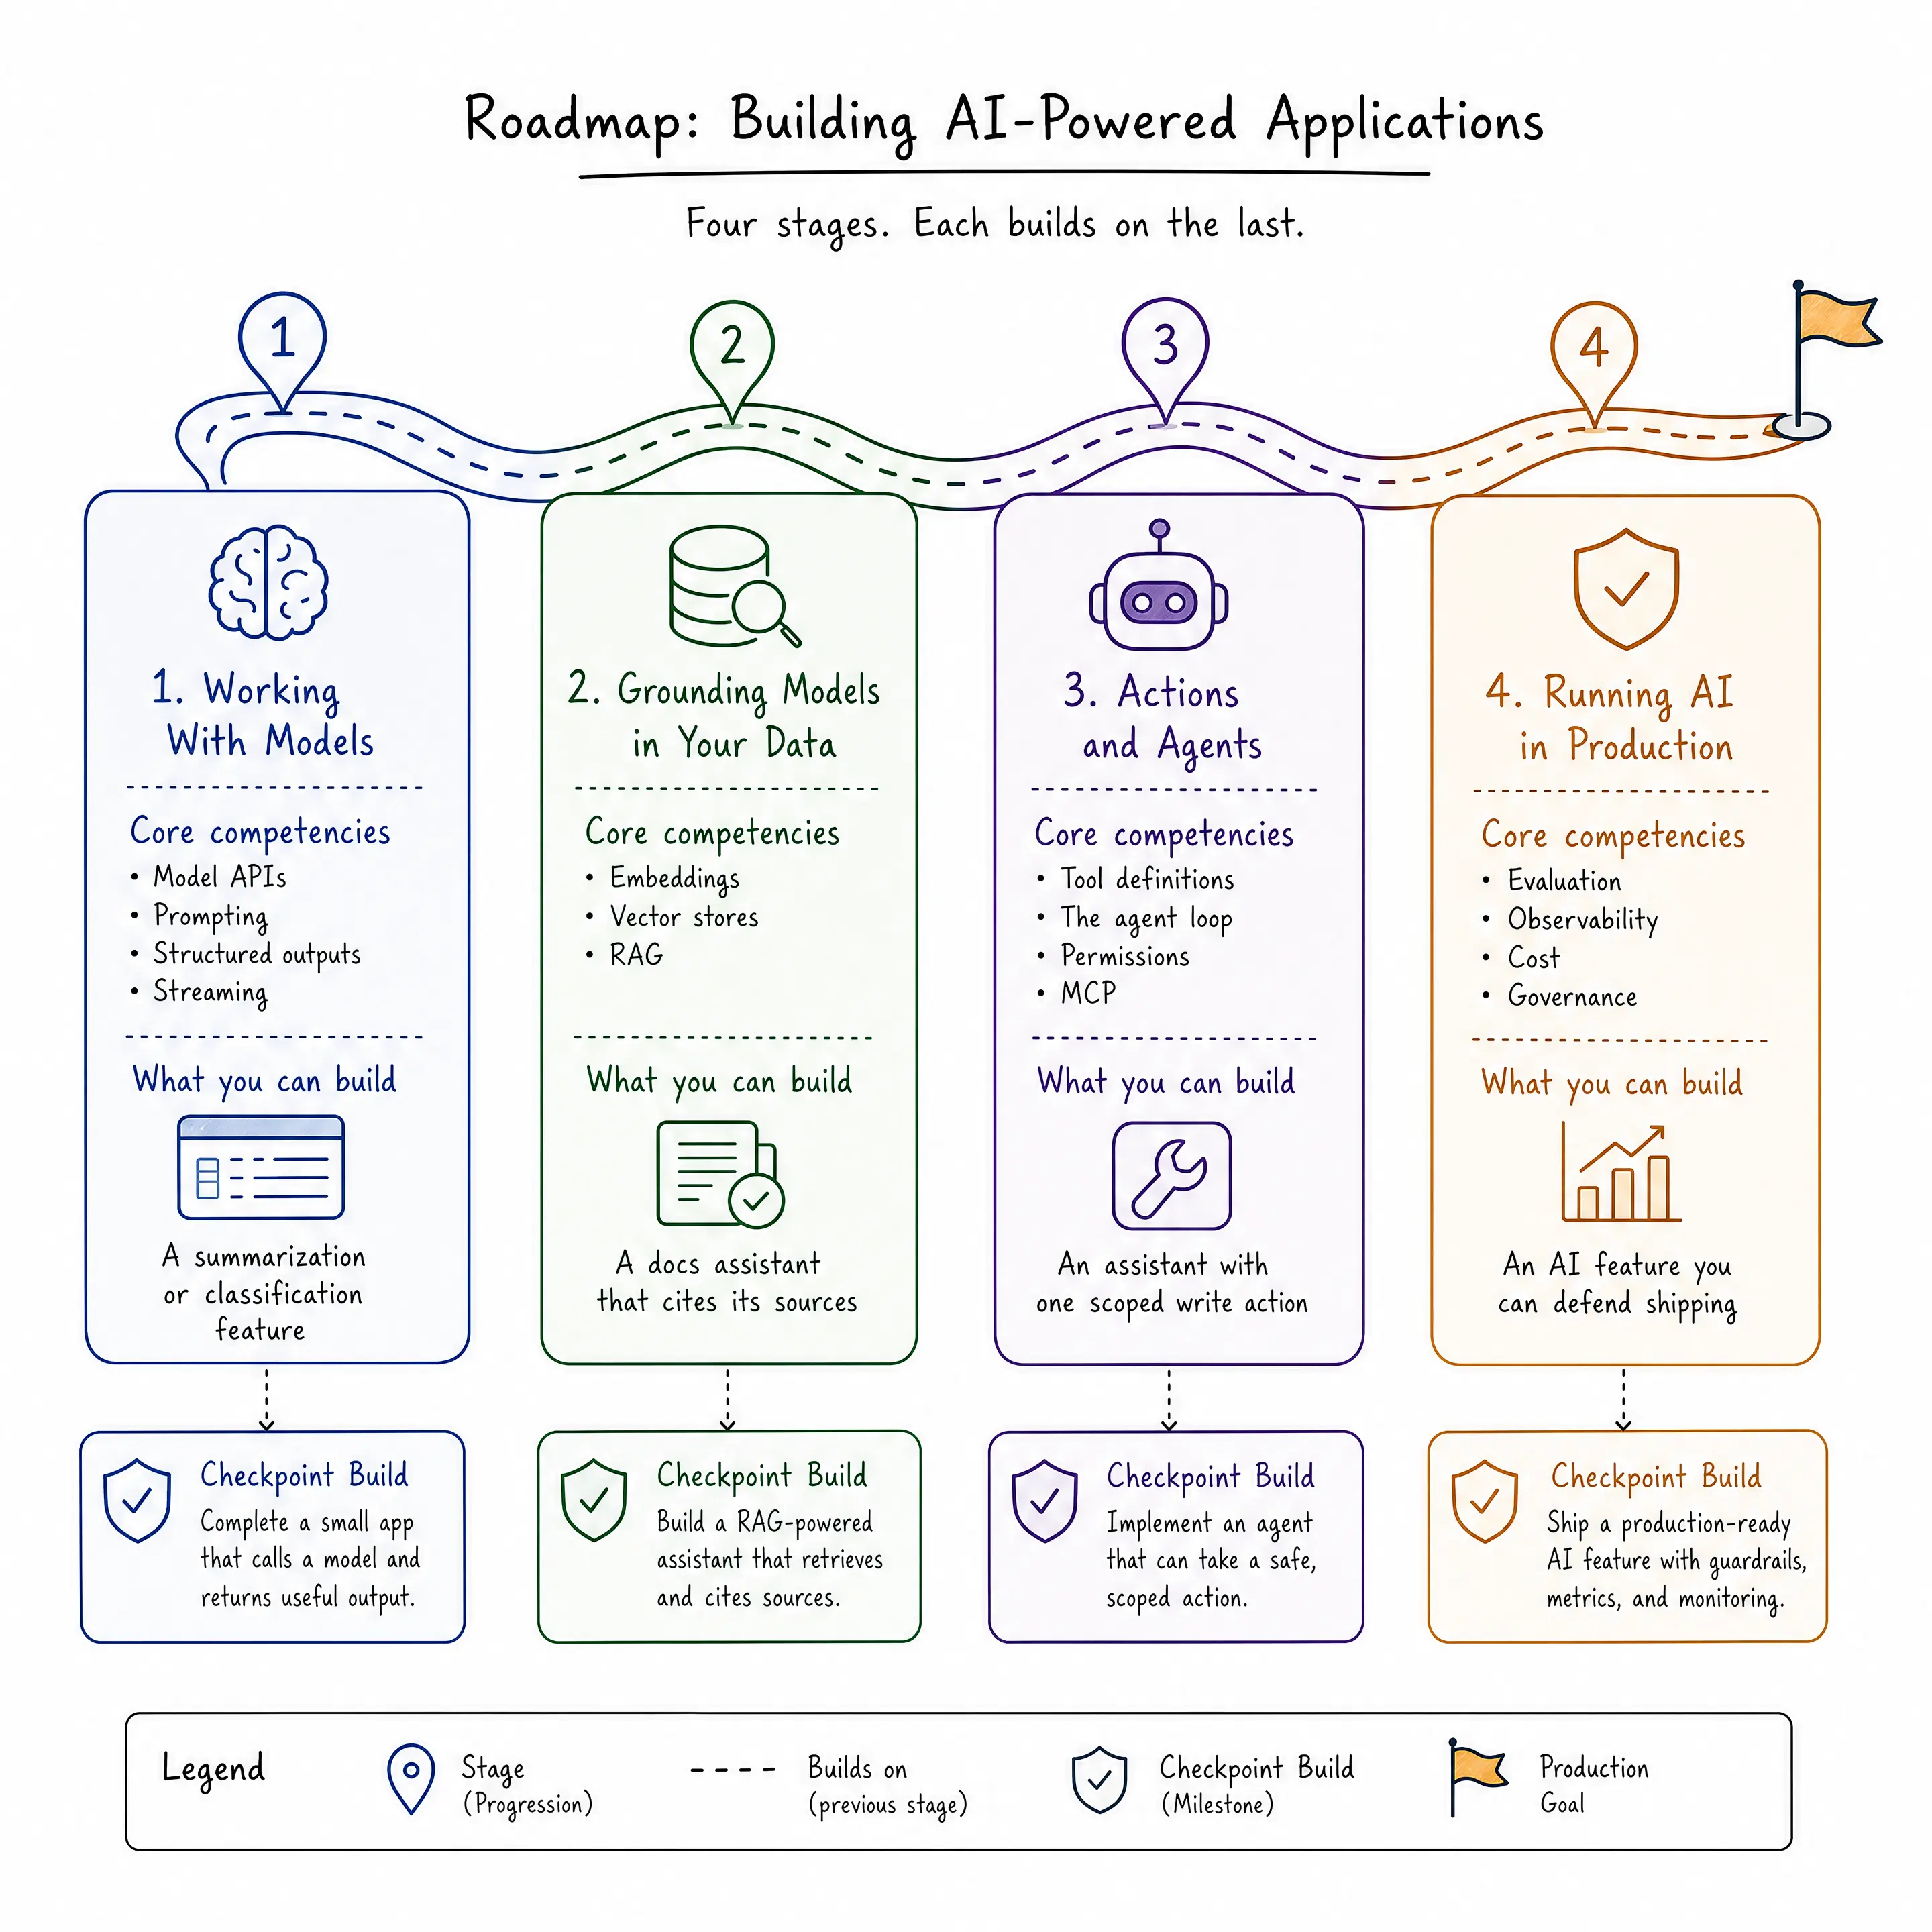
Let’s map out a route for learning the AI stack. Follow these four phases, building on your existing developer skills, to map your learning plan.
Over this AI Engineering Basics series so far, we’ve covered the layers of the modern AI stack, the architecture patterns behind AI features, the components that surround a prompt, and the agent layer now growing between frontend and backend.
Knowing the concepts is one thing. Figuring out what to learn first, and how to tell when we’ve learned it, is the part this article takes on. (This post gives you an overall map of what you need to learn and how it builds on your skills as a developer; it does not provide the in-depth training itself.)
AI engineering is an integration discipline, so most of it builds directly on skills full-stack developers already have. We’ll move through four stages, and each one names the competencies to learn and the tools worth reaching for.
How the Roadmap Is Organized
There are four stages, and each one ends with something concrete to build.
| Stage | Core competencies | What you can build after it |
|---|---|---|
| 1. Working with Models | Model APIs, prompting, structured outputs, streaming | A summarization or classification feature |
| 2. Grounding Models in Your Data | Embeddings, vector stores, RAG | A docs assistant that cites its sources |
| 3. Actions and Agents | Tool definitions, the agent loop, permissions, MCP | An assistant with one scoped write action |
| 4. Running AI in Production | Evaluation, observability, cost, governance | An AI feature you can defend shipping |
The order is about dependency rather than a strict curriculum. Retrieval builds on model calls, actions build on both, and production work wraps around everything.
Stage 1: Working with Models
What to Learn
This foundation is calling a hosted model from a backend we own and shaping what comes back. That covers the provider APIs themselves and the craft of writing and iterating on instructions. It also covers structured output for when downstream code needs to parse the response, and streaming so users aren’t staring at a spinner.
A little understanding of the underlying theory pays off here as well. An LLM generates text by predicting the next token from everything that came before, and that one fact explains most of what we see day to day: why outputs vary between runs and why a model can state a wrong answer with complete confidence.
Alongside that, this stage builds a working feel for tokens, context windows and cost. Every feature in the later stages runs into all three.
Further Learning
- OpenAI’s Prompt engineering guide shows how to write clear instructions, provide useful examples and add the context a model needs to produce more consistent results.
- Vercel’s Builders Guide to the AI SDK uses practical exercises to show how to call models from JavaScript, return structured data and stream responses into a user interface.
Tools to Reach For
Any major provider works: OpenAI, Anthropic or Google. GitHub Models is worth knowing early because it offers a free playground and API access to a wide range of models with just a GitHub account.
What to Build
A summarization or classification feature behind your own backend endpoint, like one that takes a support ticket thread and returns a summary with a suggested priority. It’s small on purpose and proves the request flow and the instruction writing, and it makes the cost math real without any other moving parts.
Stage 2: Grounding Models in Your Data
What to Learn
A model’s built-in knowledge is fixed at training time, so the second stage is retrieval: getting our own content in front of the model at request time. The pieces are embeddings (text represented as vectors that capture meaning), a vector store to search them, chunking strategies for splitting documents and the RAG pattern that ties them together.
Retrieval has a user-facing side too. Grounded answers should cite their sources and admit when the content has no answer.
Further Learning
- The Progress Telerik AI Crash Course on RAG explains how documents are divided into chunks, converted into embeddings and searched by meaning.
- OpenAI’s Citation Formatting guide explains how to give each retrieved passage a stable source identifier and instruct a model to cite it.
Tools to Reach For
pgvector adds vector search to a Postgres database we already run, and managed stores like Pinecone take over the operational side. For teams that would rather not build the pipeline at all, governed retrieval platforms like Progress Agentic RAG handle it from ingestion and permissions through to citations.
What to Build
A documentation assistant that answers only from your own content and cites the passages it used. Building it means deciding what the model should retrieve for a given request and figuring out how to keep it from answering beyond the sources. A good sign it’s working: the assistant says the docs don’t cover something instead of guessing.
Stage 3: Actions and Agents
What to Learn
The third stage moves models from answering to acting. The core skill is defining tools: operations with names and typed parameters, plus descriptions that carry the boundaries. The description is what the model reads when deciding whether an action applies. Tool calling runs as a loop: the model requests a call, our code validates and runs it, and the result feeds the next decision.
Agents also need limits. Scoped permissions let them read broadly and write narrowly, and human approval checkpoints sit in front of anything hard to reverse. The Model Context Protocol (MCP) belongs here too, as the standard for how agents discover and call tools.
Further Learning
- OpenAI’s Function calling guide shows how to define a tool with typed parameters, receive a tool request from the model, execute the operation in application code and return the result to the model.
- The official Build an MCP server tutorial walks through creating a server that exposes callable tools and connecting it to an MCP host. Examples are available for TypeScript, Python and several other languages.
Tools to Reach For
Every major provider supports tool calling through the same API we learned in Stage 1 (Working with Models), so no new platform is required to start. The MCP documentation and SDKs are the place to learn the protocol, and orchestration frameworks like Progress Forge help once workflows grow past a single loop.
What to Build
An assistant with exactly one write action behind a confirmation step, like a project assistant that can move tasks to the next sprint after we approve the list. One action is all it takes to run into every hard part: the definition, the permission scope, the approval UI and the log of what ran. When we can pull up that log and explain what the agent did and why, this stage is done.
Stage 4: Running AI in Production
What to Learn
Everything up to this point can be demoed in a week. This stage is about what happens after real users show up. Model outputs change from run to run, so testing becomes evaluation: building a set of graded examples and scoring the system against them after every change.
Observability follows. Each request gets traced from retrieval and tool calls through to the final answer, so failures can be reconstructed.
The remaining competencies are cost monitoring and the security and governance basics. Token spend scales with usage in ways traditional features don’t, and the security questions come down to what data reaches the model and who is allowed to trigger which actions.
Further Learning
The Progress Telerik How to Trace and Debug AI Agents in Production webinar shows how tracing helps us understand what an AI agent actually did when something goes wrong. It also covers evaluating answers, catching prompt injection and finding the calls responsible for slow responses or unexpected costs.
Tools to Reach For
Progress Agent Engineering, an AI observability platform, shows where workflows break, what they cost and whether outputs are good enough to ship. It is built for teams working in .NET, Python and JavaScript.
What to Build
Not a new feature this time. Wrap the assistant from the earlier stages in an eval suite of 20 or 30 graded examples and full request tracing, then change the prompt and watch the scores move. The goal is a workflow where a change ships with score evidence attached rather than a hunch.
Skills That Cut Across Every Stage
Some competencies don’t belong to any single stage. Four of them show up everywhere.
AI-Native UX Judgment
This is knowing when to show a confidence indicator, where a human-in-the-loop moment belongs, when chat is the wrong interface for the job and how to present sources so users can check an answer. A model call that works can still ship as a bad feature, and the difference is usually this judgment rather than the engineering.
Component libraries have started shipping these patterns ready-made, like the Progress KendoReact Conversational UI components, which leaves the judgment calls to us instead of the widget-building.
A Security Instinct
Every input a model reads is a potential instruction, which is what makes prompt injection a new class of attack. Every piece of context we assemble is also data leaving our boundary. Deciding what may reach the model and what its output is allowed to trigger is a per-feature decision, and it starts in Stage 1 (Working with Models) rather than arriving with Stage 4 (Running AI in Production).
Designing for Non-Determinism
The same request can produce different outputs on different runs, and ever-stricter prompts won’t make that go away. Non-determinism is a design constraint rather than a bug. Designing for it means constraining the output format and validating everything the model returns. It also means building a fallback for the times the model returns something unusable.
Working with Coding Agents
Using AI-assisted development tools daily doubles as study for this roadmap. Working with a coding agent in Cursor, Claude Code, OpenAI Codex or GitHub Copilot is a live lesson in how models handle context and instructions, and that intuition transfers directly to the features we build.
The tooling also runs in the other direction. Libraries are starting to ship MCP servers of their own, like the Telerik and Kendo UI MCP Server, which gives a coding agent specialized knowledge of the component library it’s generating code for. That’s the same tool discovery idea from Stage 3 (Actions and Agents), applied to our own workflow.
Wrap-up
This series opened with the claim that the full-stack role is expanding rather than being replaced. The articles since have covered the stack, the architectures, the components beyond the prompt and the agent layer.
This roadmap turns those ideas into things to build. None of the checkpoints need special infrastructure or a research background, and none of them are bigger than a side project.
The series continues from here as well. Upcoming articles will go deeper into the territory each stage opens: designing AI-powered experiences, agent engineering, running AI in production and AI-assisted development itself.
For more on building AI-powered applications and agents with Progress, check out the following resources:
Hassan Djirdeh
Hassan is a senior frontend engineer and has helped build large production applications at-scale at organizations like Doordash, Instacart and Shopify. Hassan is also a published author and course instructor where he’s helped thousands of students learn in-depth frontend engineering skills like React, Vue, TypeScript and GraphQL.
Related Posts
Comments
All articles
Topics
Web MobileMobile
Desktop
Design
Productivity
People